Method
How I test
Every model gets the same machine, the same tests and its own model card's settings. Here is exactly what that means. Every launch is in the configs.
The machine
| GPU | NVIDIA RTX PRO 6000 Blackwell (sm_120), 96 GB VRAM (~92 GB usable) |
| CPU | AMD Ryzen 9 9950X, 16 cores / 32 threads |
| RAM | 96 GB DDR5 dual channel (~91 GB usable) |
| Power cap | 400 W |
| Driver | driver 595.99.02, CUDA 13.2 |
The same for every model
- Cold cache. The server's cache is flushed before every test, and the speed and context retention tests read every prompt from scratch.
- Thinking on, at the highest effort the model card lists (xhigh), except where a test says off: tool use, context retention and Spec-Bench.
- The card's sampler: temperature, top_p and the rest come from the model's own card, never tuned by me.
- The full window: 262,144 tokens, one model on the GPU at a time.
- Compaction allowed in the agent tests: when a session reaches 151,552 tokens, the agent summarises it and carries on, so a long session never overflows the window.
- One run per model per test, with the same prompts and the same time limits.
The tests
Performance
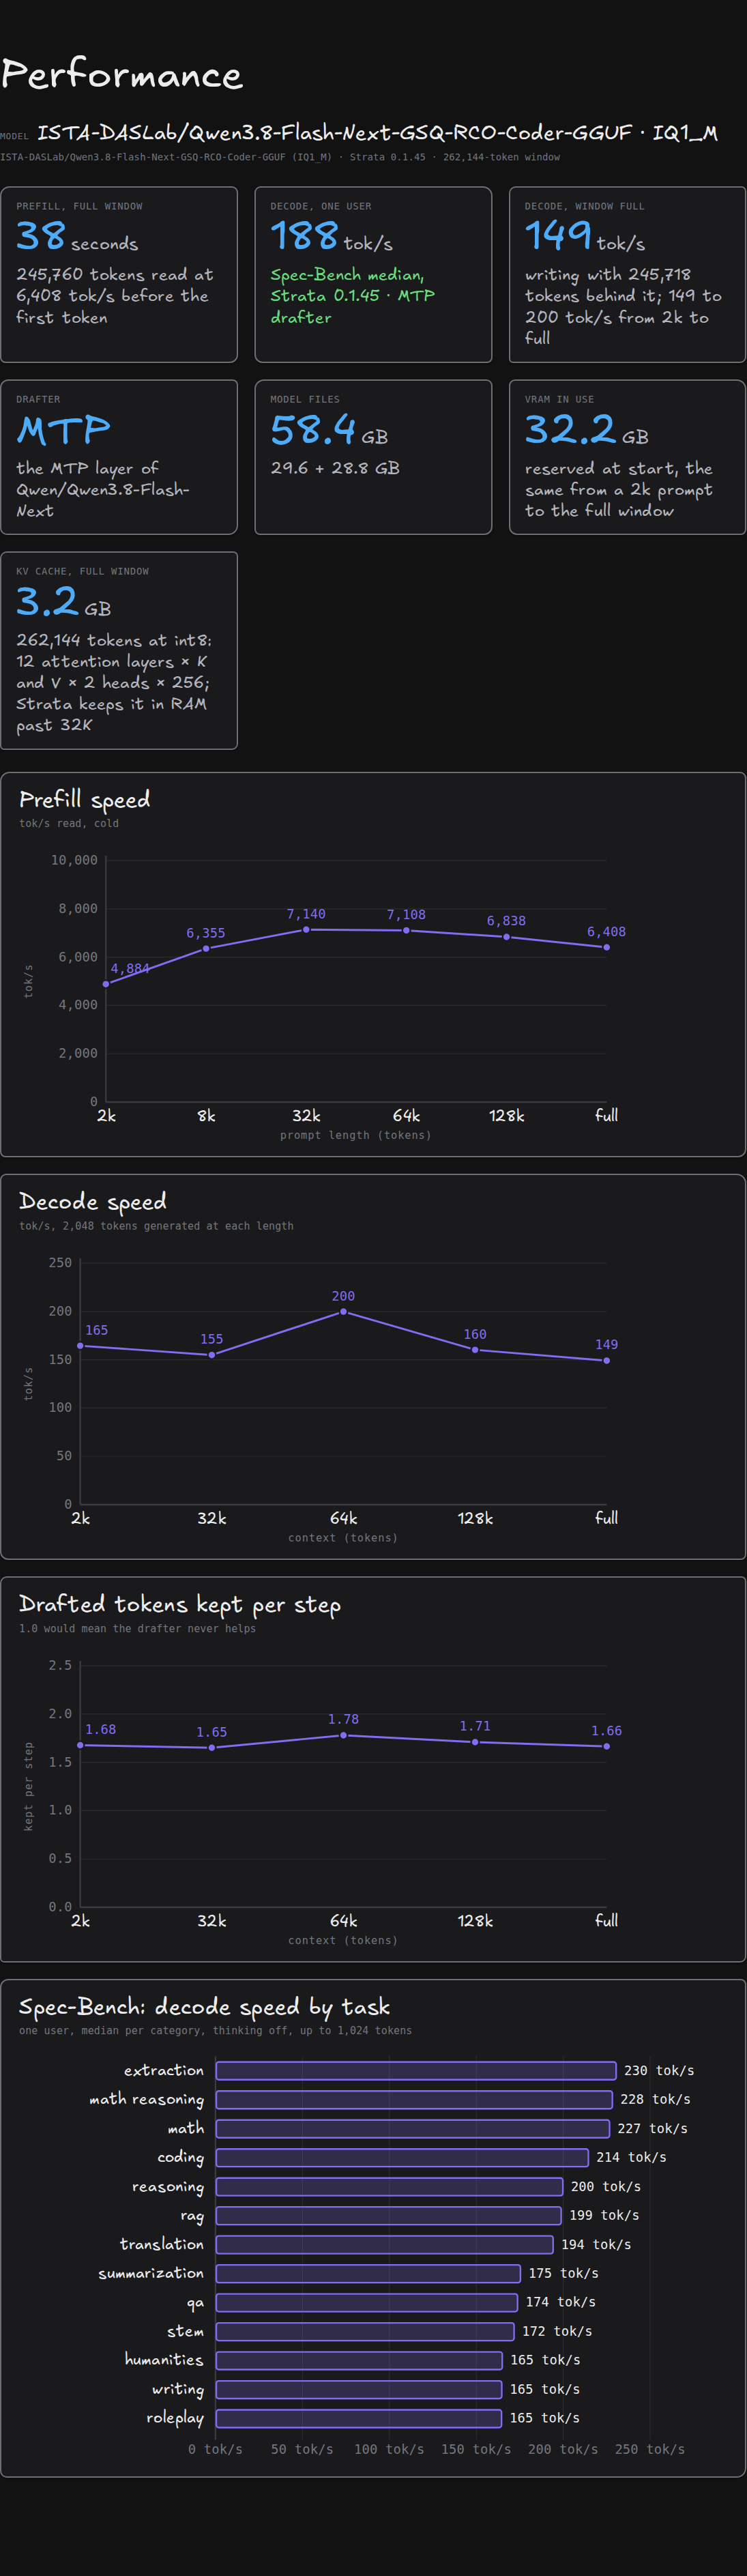
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: Prefill, full window · not one to one, no winner
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | 38 s |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | 22.4 s |
- Thinking
- off for Spec-Bench, raw requests for prefill and decode
- Time limit
- 150 min for the whole test
- Cache
- cold on every request
- Agent
- raw requests, no agent
- Compaction
- none
- Internet
- no
Battle arena
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: Open arena score (1 blind army)
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | 759 / 1000 |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | 477 / 1000 |
- Thinking
- on, xhigh effort
- Output cap
- the window minus the prompt minus 16,384
- Time limit
- 300 min for the whole test
- Cache
- flushed before the test
- Agent
- one JSON answer per ask
- Compaction
- none
- Internet
- no
Tool use
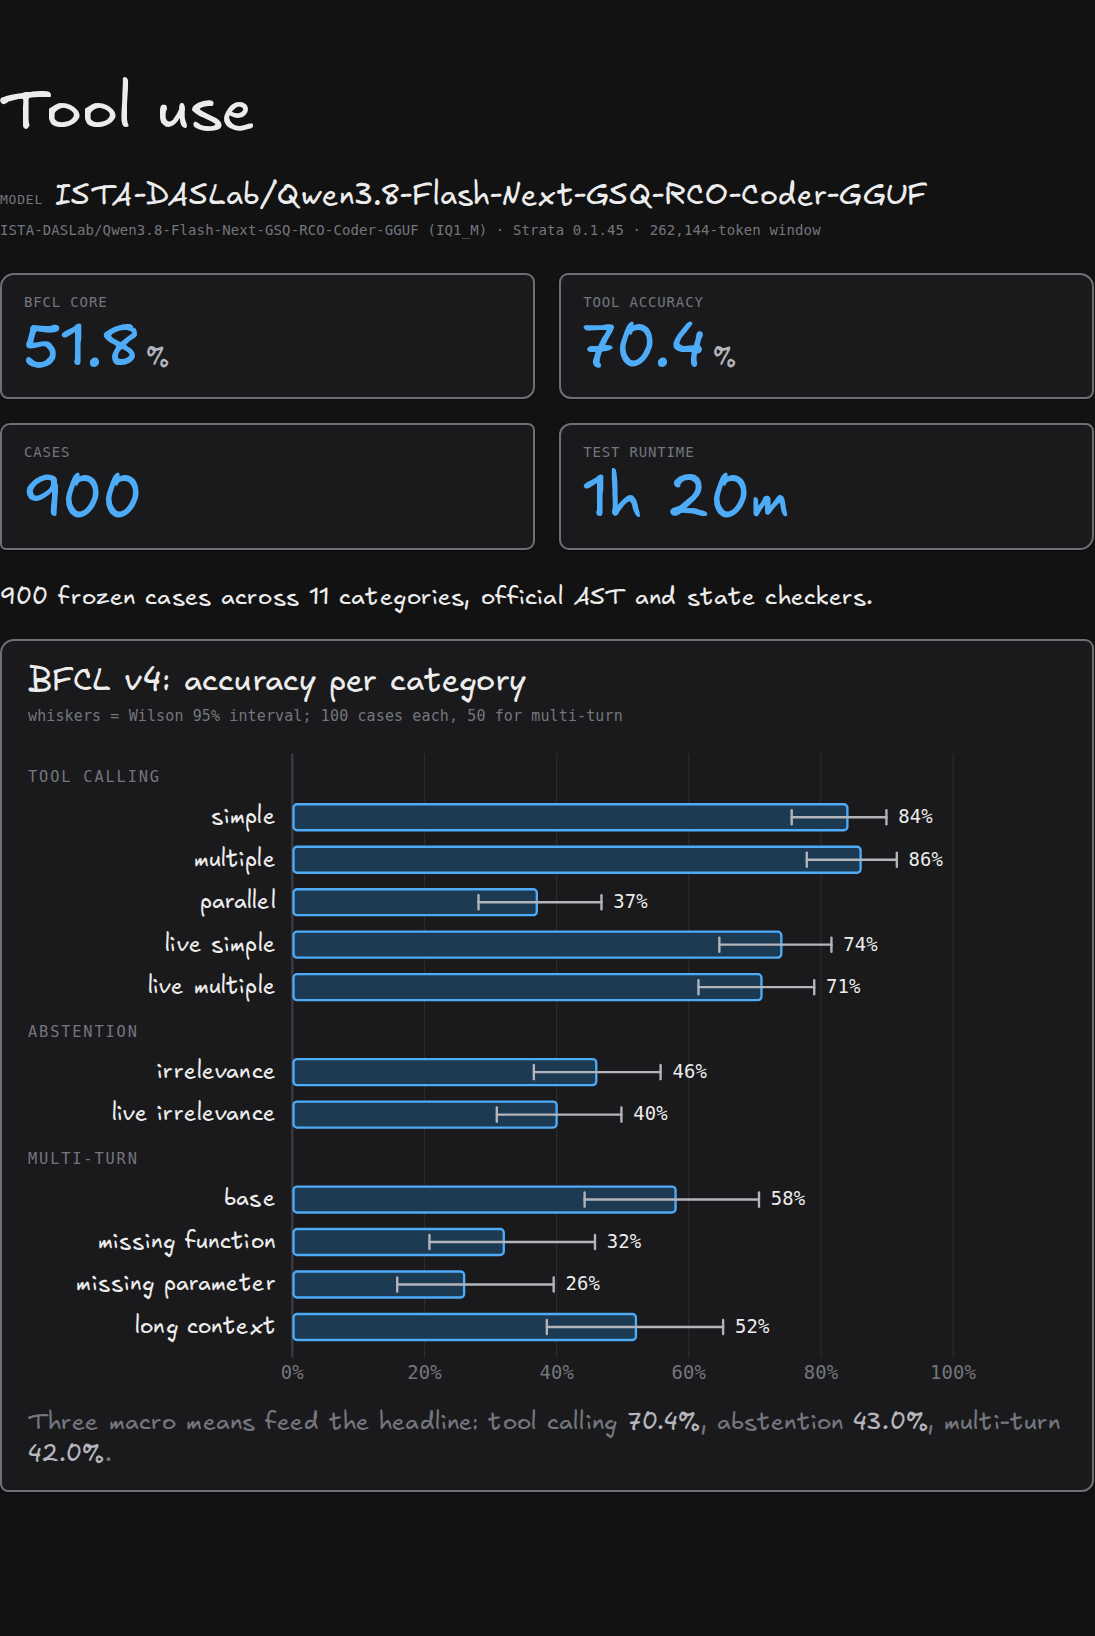
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: BFCL core
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | 51.8 % |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | 64.5 % |
- Thinking
- off
- Output cap
- 32,768 tokens per answer
- Time limit
- 120 min for the whole test
- Cache
- flushed before the test
- Agent
- function calls, BFCL's own harness
- Compaction
- none
- Internet
- no
CAPTCHA
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: Solved
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | 30 / 40 |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | 21 / 40 |
- Thinking
- on, xhigh effort
- Output cap
- 110,592 tokens per answer
- Time limit
- 7 min per puzzle counts (the cap every model had)
- Cache
- flushed before the test
- Agent
- Pi agent driving a real browser: clicks and screenshots only
- Compaction
- allowed: Pi compacts the conversation at 151,552 tokens
- Internet
- only the puzzle site
Context retention
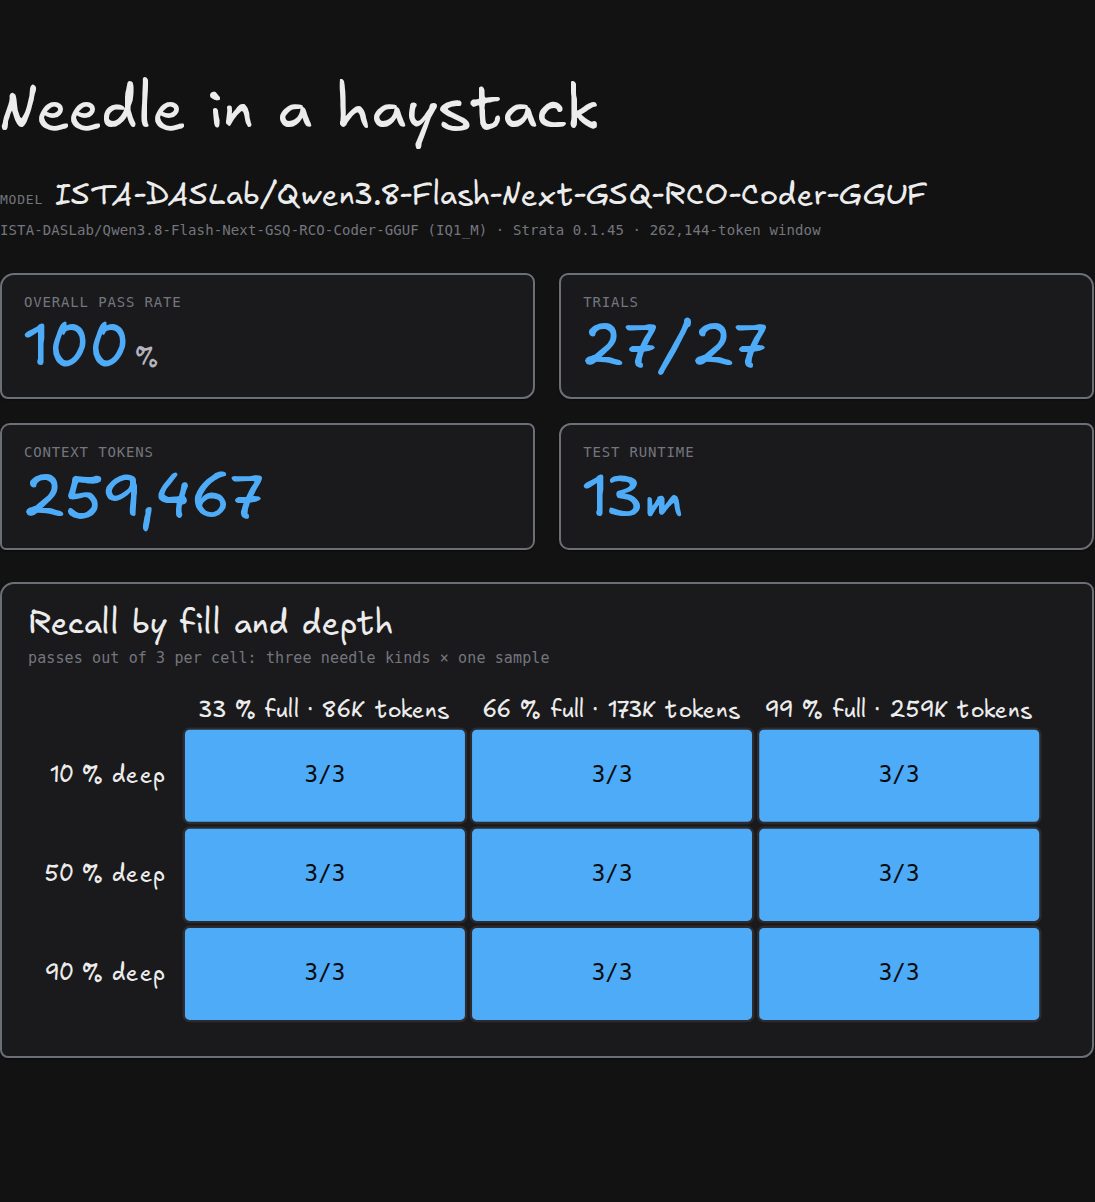
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: Recall over the grid
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | 27 / 27 100% |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | 81 / 81 100% |
- Thinking
- off
- Output cap
- 256 tokens per answer
- Time limit
- 120 min for the whole test
- Cache
- cold on every request
- Agent
- one request per question
- Compaction
- none
- Internet
- no
Drawing
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: Format checks
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | 8 / 8 |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | 8 / 8 |
- Thinking
- on, xhigh effort
- Output cap
- 110,592 tokens per answer
- Time limit
- 45 min for the session
- Cache
- flushed before the test
- Agent
- Pi coding agent: terminal and file tools
- Compaction
- allowed: Pi compacts the conversation at 151,552 tokens
- Internet
- yes
Voxel
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: by eye
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | – |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | better |
- Thinking
- on, xhigh effort
- Output cap
- 110,592 tokens per answer
- Time limit
- 150 min for the session
- Cache
- flushed before the test
- Agent
- Pi coding agent: terminal and file tools
- Compaction
- allowed: Pi compacts the conversation at 151,552 tokens
- Internet
- yes, for photos
Design
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: Hard rules
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | 7 / 7 |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | 7 / 7 |
- Thinking
- on, xhigh effort
- Output cap
- 110,592 tokens per answer
- Time limit
- 60 min for the session
- Cache
- flushed before the test
- Agent
- Pi coding agent: terminal and file tools
- Compaction
- allowed: Pi compacts the conversation at 151,552 tokens
- Internet
- no
Rube Goldberg
Example from I Tested Strata Coder So You Don't Have To: Qwen 3.8 Flash Next vs Full NVFP4 in 9 Real Tests: Ball in the cup
| ISTA-DASLab/Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF | yes |
| RadixArk/Qwen3.8-Flash-Next-NVFP4 | yes |
- Thinking
- on, xhigh effort
- Output cap
- 110,592 tokens per answer
- Time limit
- 90 min for the session
- Cache
- flushed before the test
- Agent
- Pi coding agent in a sealed folder
- Compaction
- allowed: Pi compacts the conversation at 151,552 tokens
- Internet
- no (a network call voids the run)