ukisai/Swift-1.5-Qwen3.8-27B-GSQ-RCO-GGUF IQ3_S
| PerformancePrefill, full window | 205 s |
| Tool useBFCL core | 70.7 % |
| Context retentionRecall over the grid | 27 / 27 100% |
| Battle arenaOpen arena score (1 blind army) | 362 / 1000 |
| DrawingFormat checks | 8 / 8 |
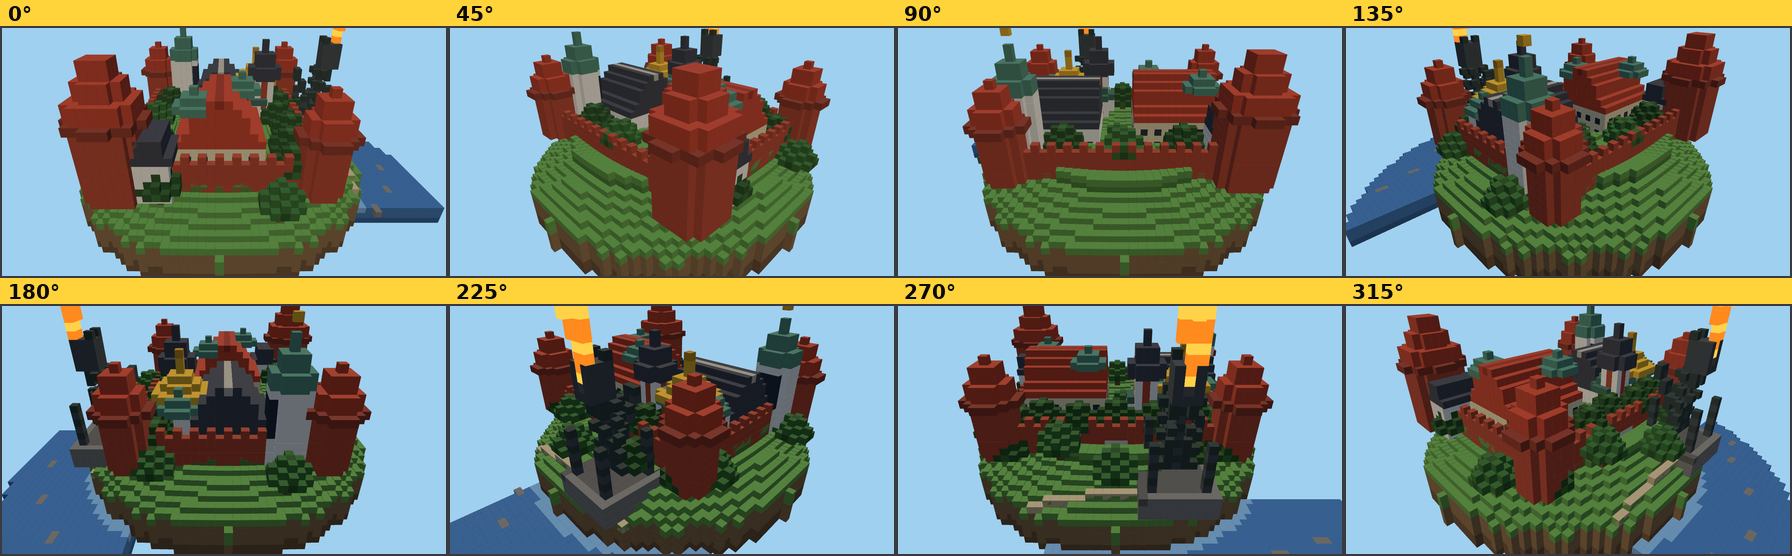
| Voxel | no result No number: the castle is only judged by eye, against another model. Its build is on its own page, under What it made. |
| DesignHard rules | 7 / 7 |
| Rube GoldbergBall in the cup | yes |
| CAPTCHASolved | 19 / 40 |
| Thinking tokenstotal over 6 tests | 1,271,767 |
| VRAM in usethe most in any test | 33.2 GB |
- One run per test, at a 400 W GPU power cap.
- The same Swift 1.5 weights as ukisai/Swift-1.5-Qwen3.8-27B-GGUF, in UkisAI's mixed-precision GSQ-RCO quant at IQ3_S, the repo's biggest tier.
Speed
Prefill is how fast it reads the prompt, decode how fast it writes. Both on a cold cache, one request at a time, as the prompt grows to the full window.
Prefill, tokens per second
prompt length, tokens
Decode, tokens per second
context already in the window, tokens
With a drafter, decode speed rises and falls with how many drafted tokens the model accepts per step (hover or tap a point).
Tool use
BFCL, the Berkeley function-calling benchmark: does it call the right tool with the right arguments, say no when no tool fits, and keep it up over a conversation.
Calling the right tool
Saying no
Multi-turn
Context retention
A fact hidden in a long document, at three depths, in three kinds (a code, a contradiction, a date). Can it still find it as the document fills the window?
| window filled | fact at 10 % | fact at 50 % | fact at 90 % |
|---|---|---|---|
| 33 % | 3 / 3 | 3 / 3 | 3 / 3 |
| 66 % | 3 / 3 | 3 / 3 | 3 / 3 |
| 99 % | 3 / 3 | 3 / 3 | 3 / 3 |
control at 8,192 tokens: 3 / 3
Battle arena: the gauntlet
15 fixed battles against a known enemy, 200 runs each in the simulator (100 seeds, sides swapped). It won 13 of the 15, a win being more than half of the runs.
Easy
Medium
Hard
CAPTCHA
40 puzzles, 2 of each of 20 kinds, solved in a real browser with the mouse and keyboard. A solve counts within 7 minutes, as for every model.
By kind
filled: solved within 7 min · hollow: not
What it made
Drawing (SVG)
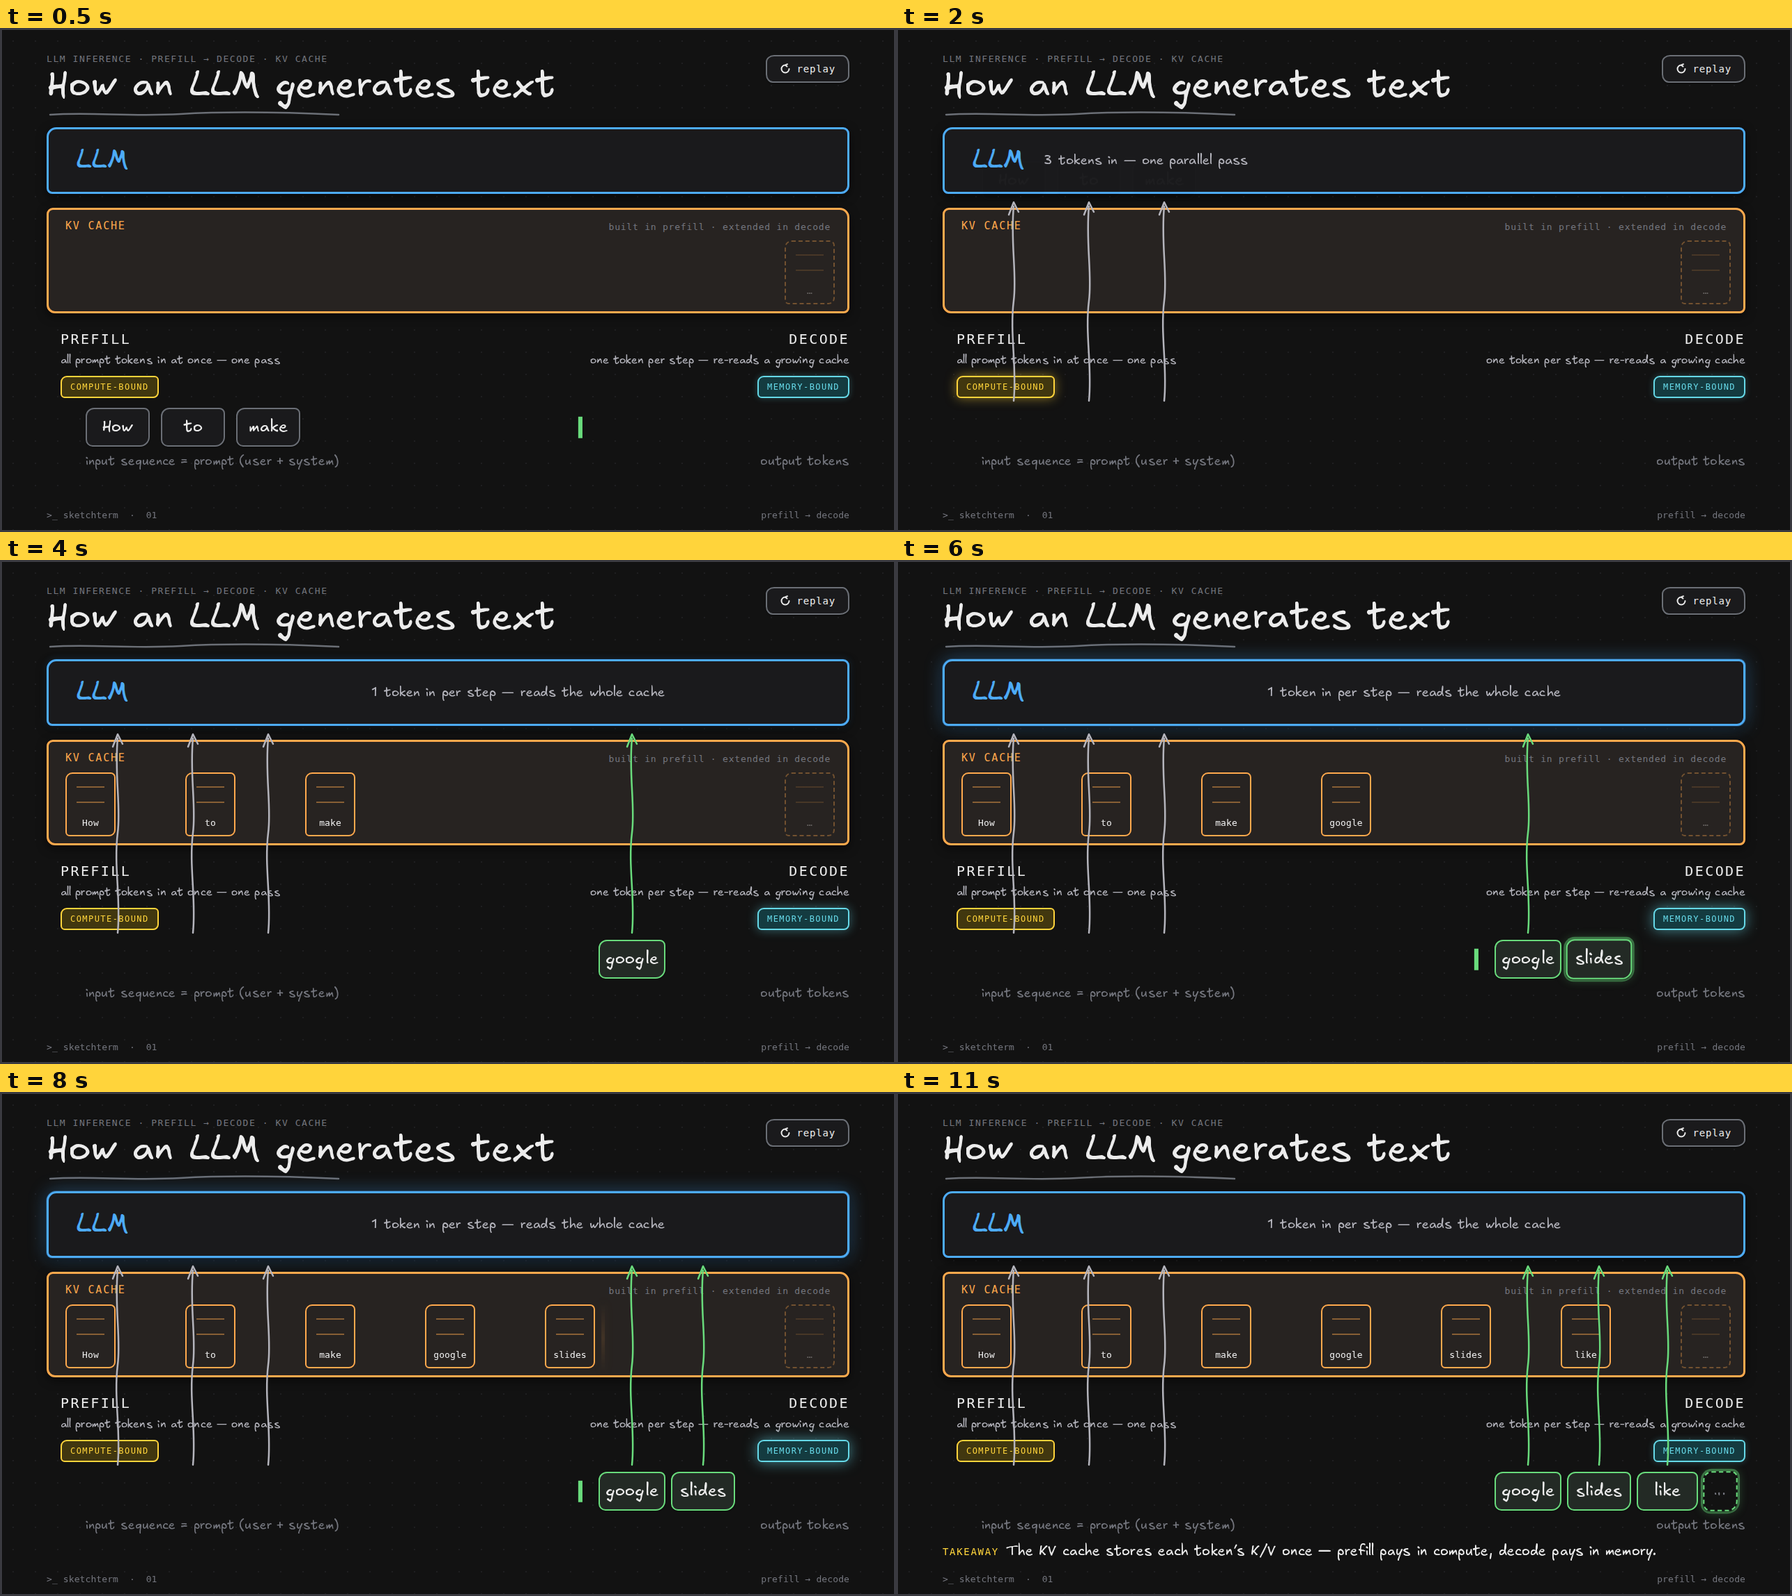
Design board, six moments
Voxel Wawel, eight angles
The setup it ran with
| Engine | llama.cpp b11552-23b0202a1 |
| Quantization | IQ3_S |
| Context window | 262,144 tokens |
| KV cache | q8_0 |
| Drafter | DFlash, incoai/Qwen3.8-27B-DFlash2-GGUF |
| Sampler (from the model card) | temperature 1.0, top_p 0.95, top_k 20, min_p 0.0, presence_penalty 0.0 |
| Reasoning effort | xhigh |